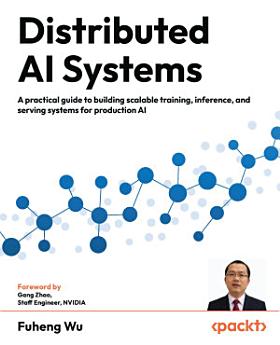
About this ebook
- Understand GPU hardware, high-speed interconnects, and parallelism strategies
- Hands-on exercises at the end of every chapter
- Learn distributed training with resource-optimized techniques
- Deploy high-performance inference with advanced optimization and memory management
- Build production serving stacks with job schedulers, orchestration, and observability
- Estimate memory and compute requirements for training and inference
- Understand GPU hardware, interconnects, and parallelism strategies
- Implement distributed training with parallel and sharded techniques
- Build production inference systems with batching and memory management
- Deploy via cluster orchestration with optimized GPU scheduling
- Create production serving stacks with routing and observability
- Benchmark distributed systems using industry-standard methodologies
- Explore emerging model trends, scaling strategies, and future paths
This book is designed for ML engineers, AI researchers, and DevOps professionals who need to train or serve large AI models at scale. Platform engineers, HPC cluster administrators, and cloud architects will also find it valuable for advancing their skill sets. A basic understanding of Python and PyTorch is required to get started. Prior experience with distributed systems, cluster schedulers, or container orchestration is helpful but not necessary - the book introduces these concepts from the ground up, beginning with resource estimation, data preparation, and hardware fundamentals.
Discover more
About the author
Henry (Fuheng) Wu is a Principal Machine Learning Tech Lead at Oracle's Generative AI organization, specializing in distributed training, large-scale inference, and GPU systems. He has delivered core components of Oracle's Vision and Document Understanding AI services, and co-authored a Microsoft and Oracle blog on high-performance deep learning. He has contributed to open-source projects including SGLang, genai-bench, pyLLaMA, chatLLaMA, and Oracle's HiQ observability system. With hands-on experience across PyTorch Distributed, DeepSpeed, Kubernetes GPU clusters, and production LLM serving, he focuses on building practical, scalable AI systems used in real-world enterprise workloads.